A B2B SaaS churn-prediction platform built as tested, gated milestones — a data-quality engine, a leakage-safe churn model, and an analytics dashboard reading real pipeline output. All data is synthetic.
Overview
Customer Intelligence Platform is a B2B SaaS churn-prediction and data-quality product, built as a sequence of tested, gated milestones rather than a single prototype: a synthetic data foundation, an automated data-quality engine, a leakage-safe churn-prediction pipeline, and an analytics dashboard that reads real pipeline output — no hand-typed numbers anywhere. The company and its data are entirely synthetic and fictional.
Problem
Churn models are easy to get impressively wrong: leak future information into training features, train on data nobody's validated, or report a confident-looking probability that's actually miscalibrated. I wanted to build the whole pipeline the way a real ML system should be — data quality gating the model, the model gated by acceptance criteria, and every dashboard number traced back to a real report rather than typed in by hand.
Approach
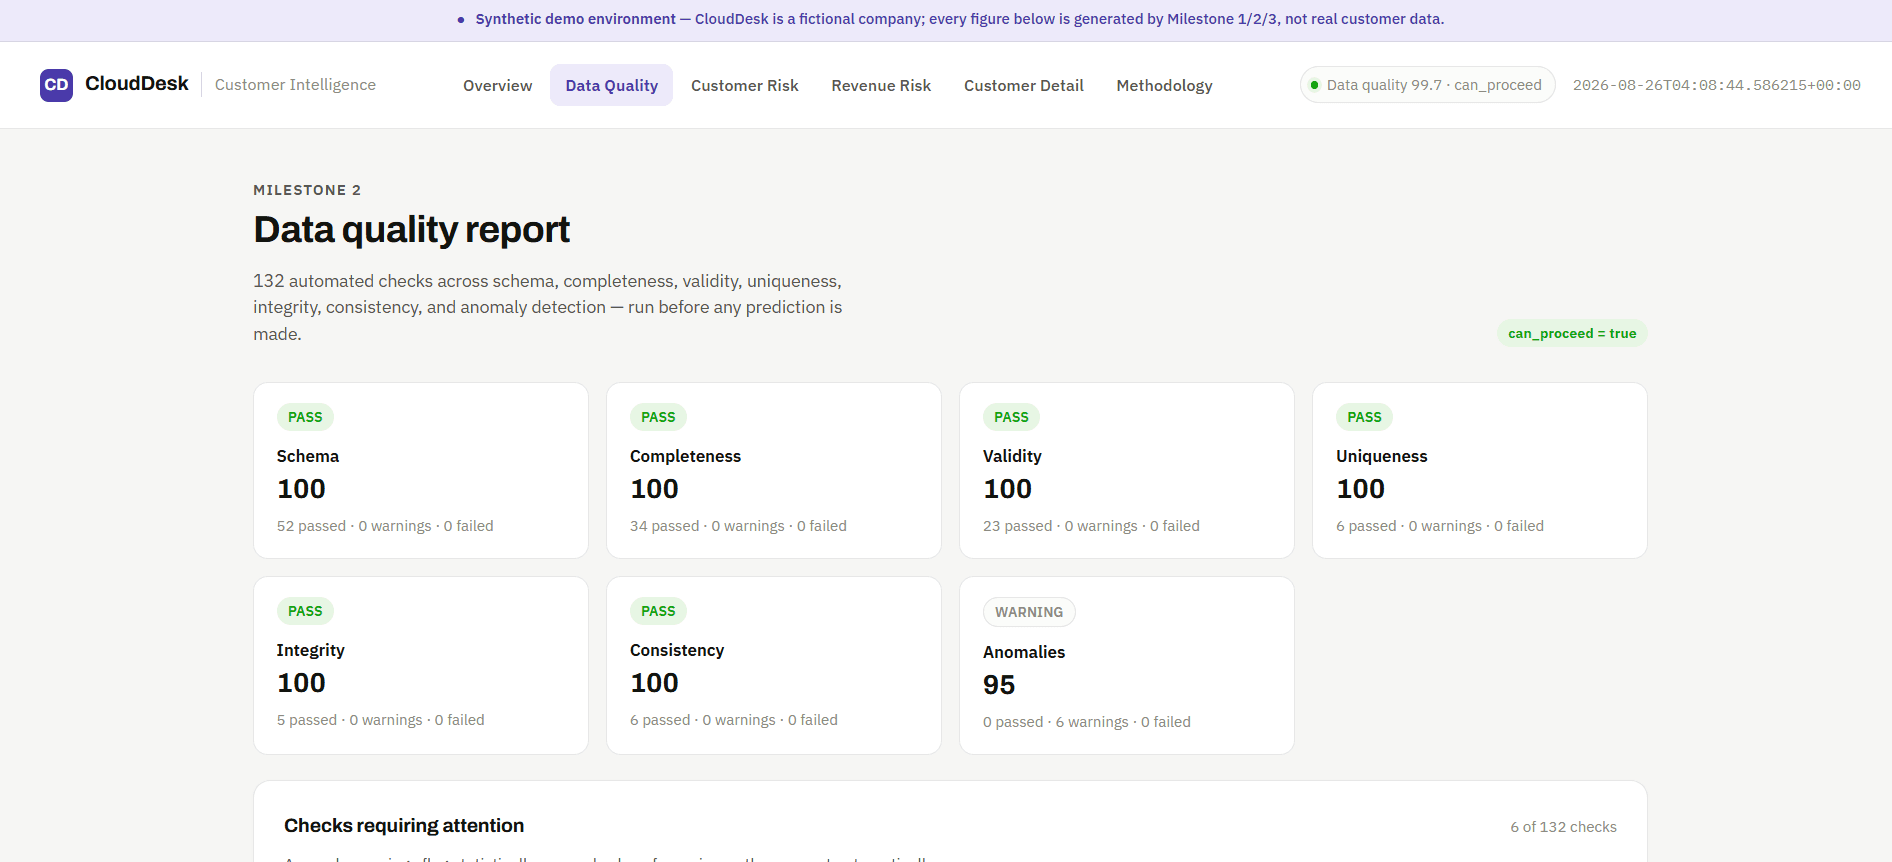
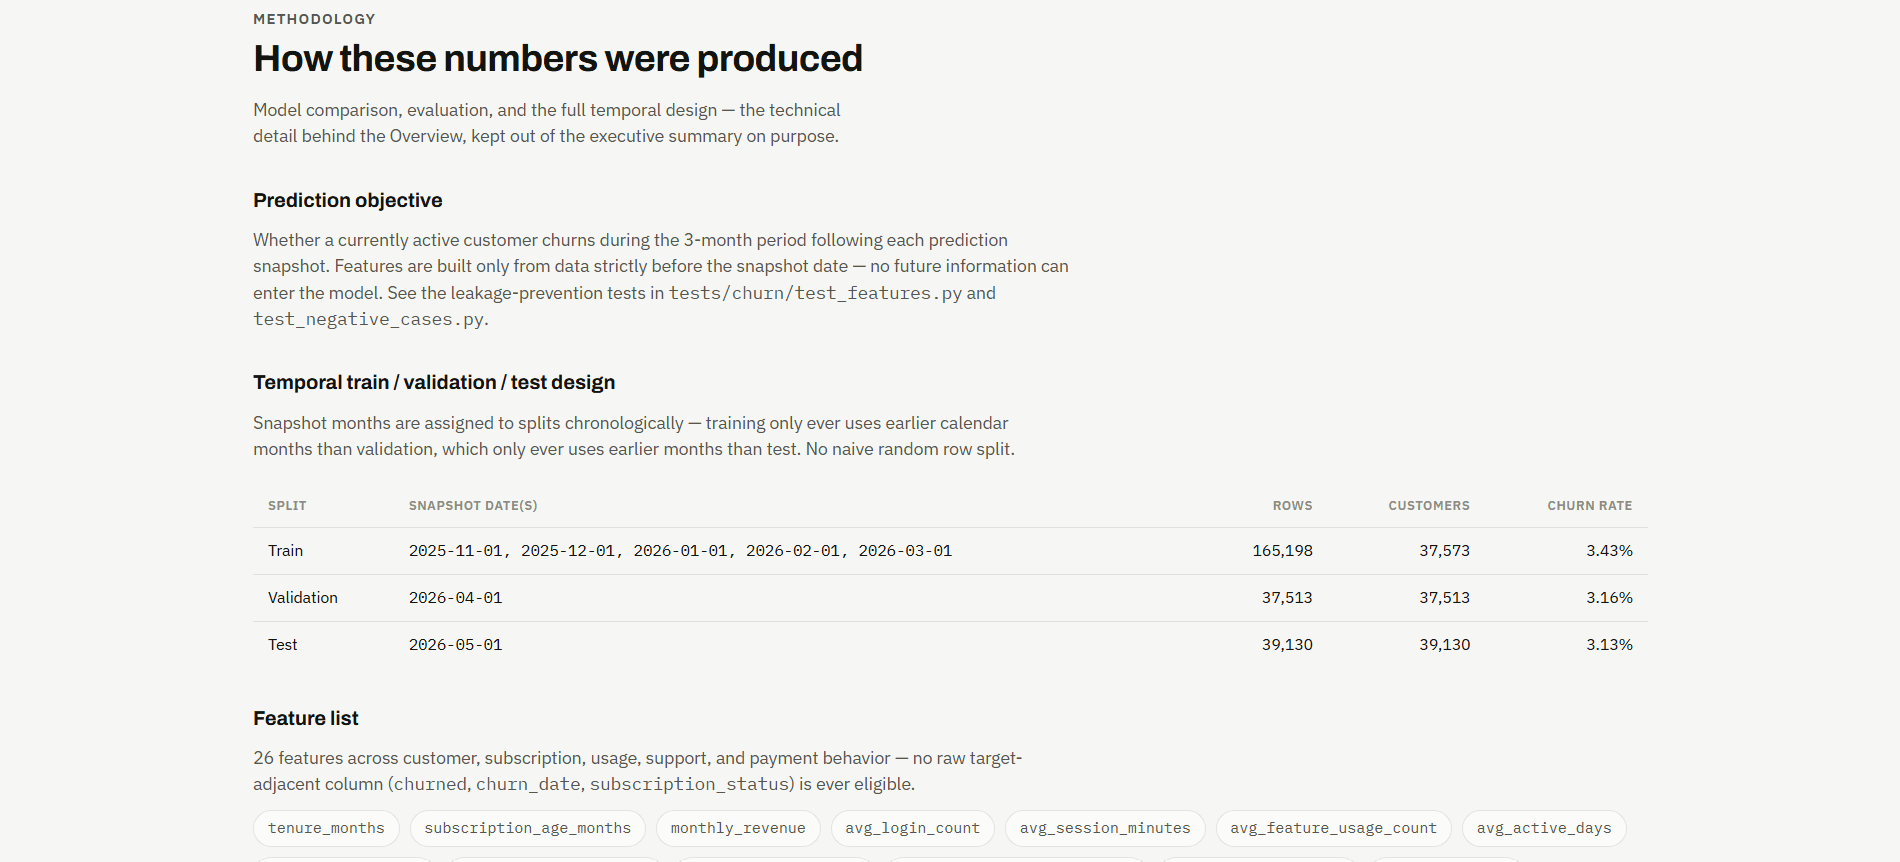
Each stage blocks the next: a data-quality engine scores incoming data across eight dimensions and produces a pass/fail gate; the churn engine refuses to train if that gate fails; every feature is time-filtered to strictly before its prediction snapshot to prevent leakage, backed by three independent leakage-prevention layers — a computation-boundary check, a forbidden-column contract and a required-feature contract — each with its own regression tests; and the model only ships as "accepted" if it clears fixed acceptance criteria. The dashboard on top reads only from the pipeline's own JSON output through one data-access layer, so there's no path for a stray hardcoded number to end up on a page.
Engineering
- Deterministic synthetic SaaS dataset generator — 50,000 customers, 12 months of usage/support/billing history
- Automated data-quality engine scoring 8 dimensions (schema, completeness, validity, uniqueness, integrity, consistency, anomaly, drift) with a hard pass/fail gate
- Leakage-safe churn model (Random Forest) with a temporal train/validation/test split and explicit, documented acceptance criteria
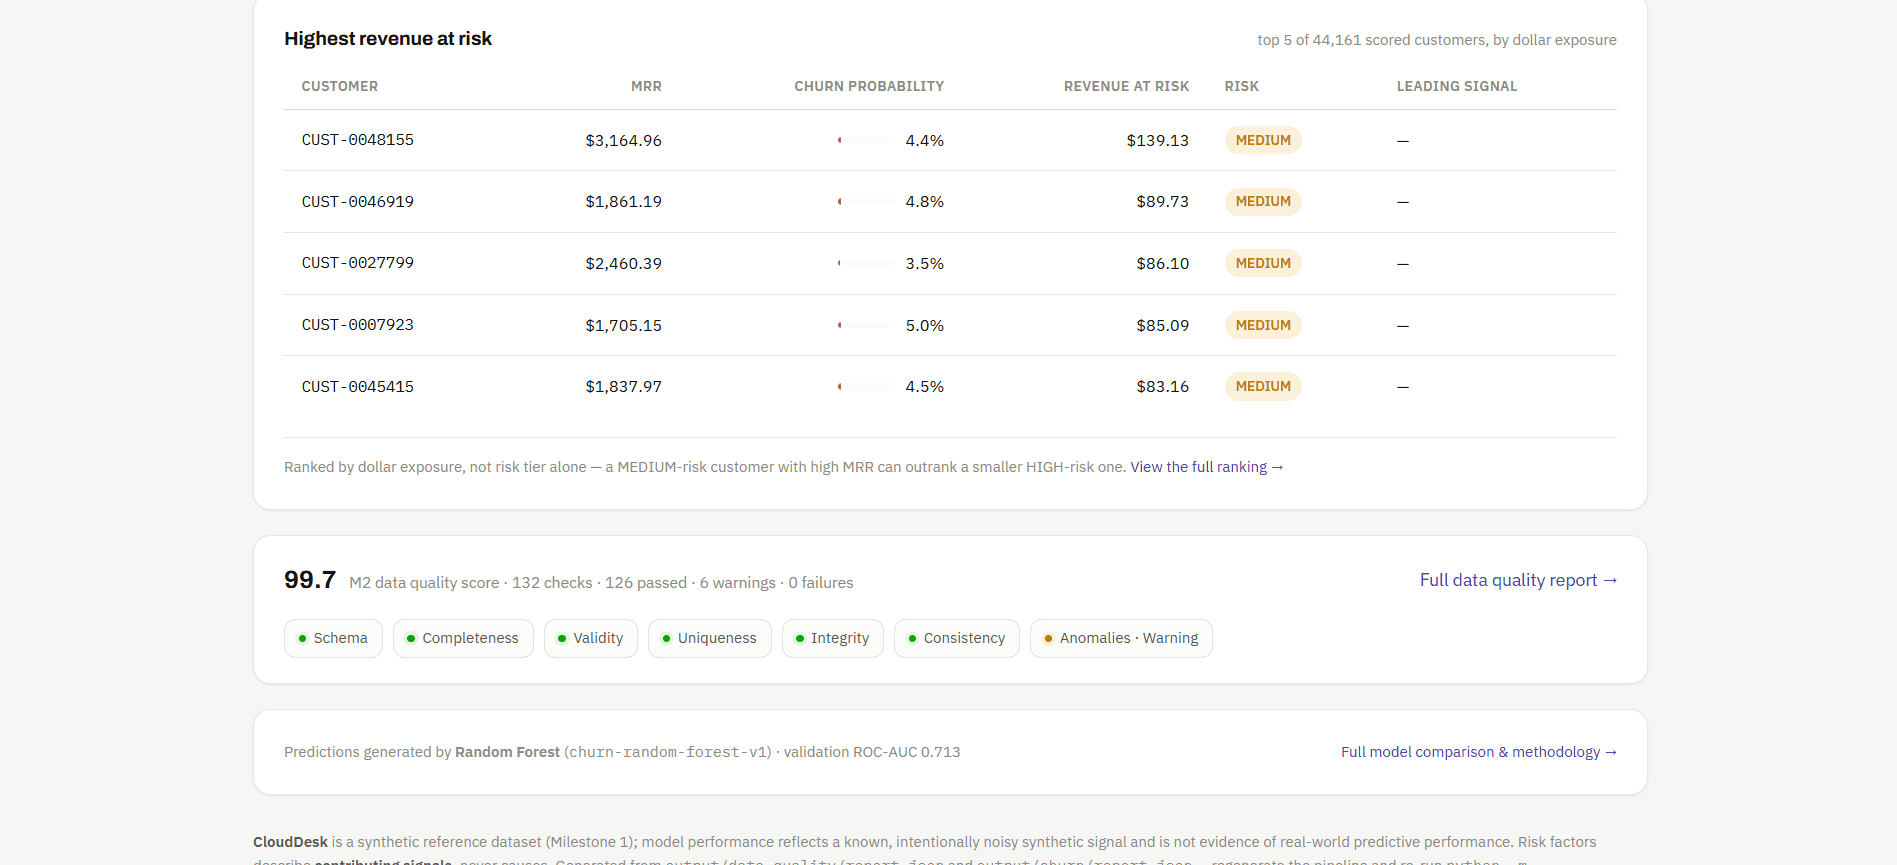
- Per-customer risk explanations and revenue-at-risk estimates generated from the model, not hand-computed
- A 6-page analytics dashboard with a colorblind-safe, dark/light-aware design system
- 256 automated tests spanning data generation, quality scoring, leakage prevention, model determinism and dashboard rendering
Result / Current State
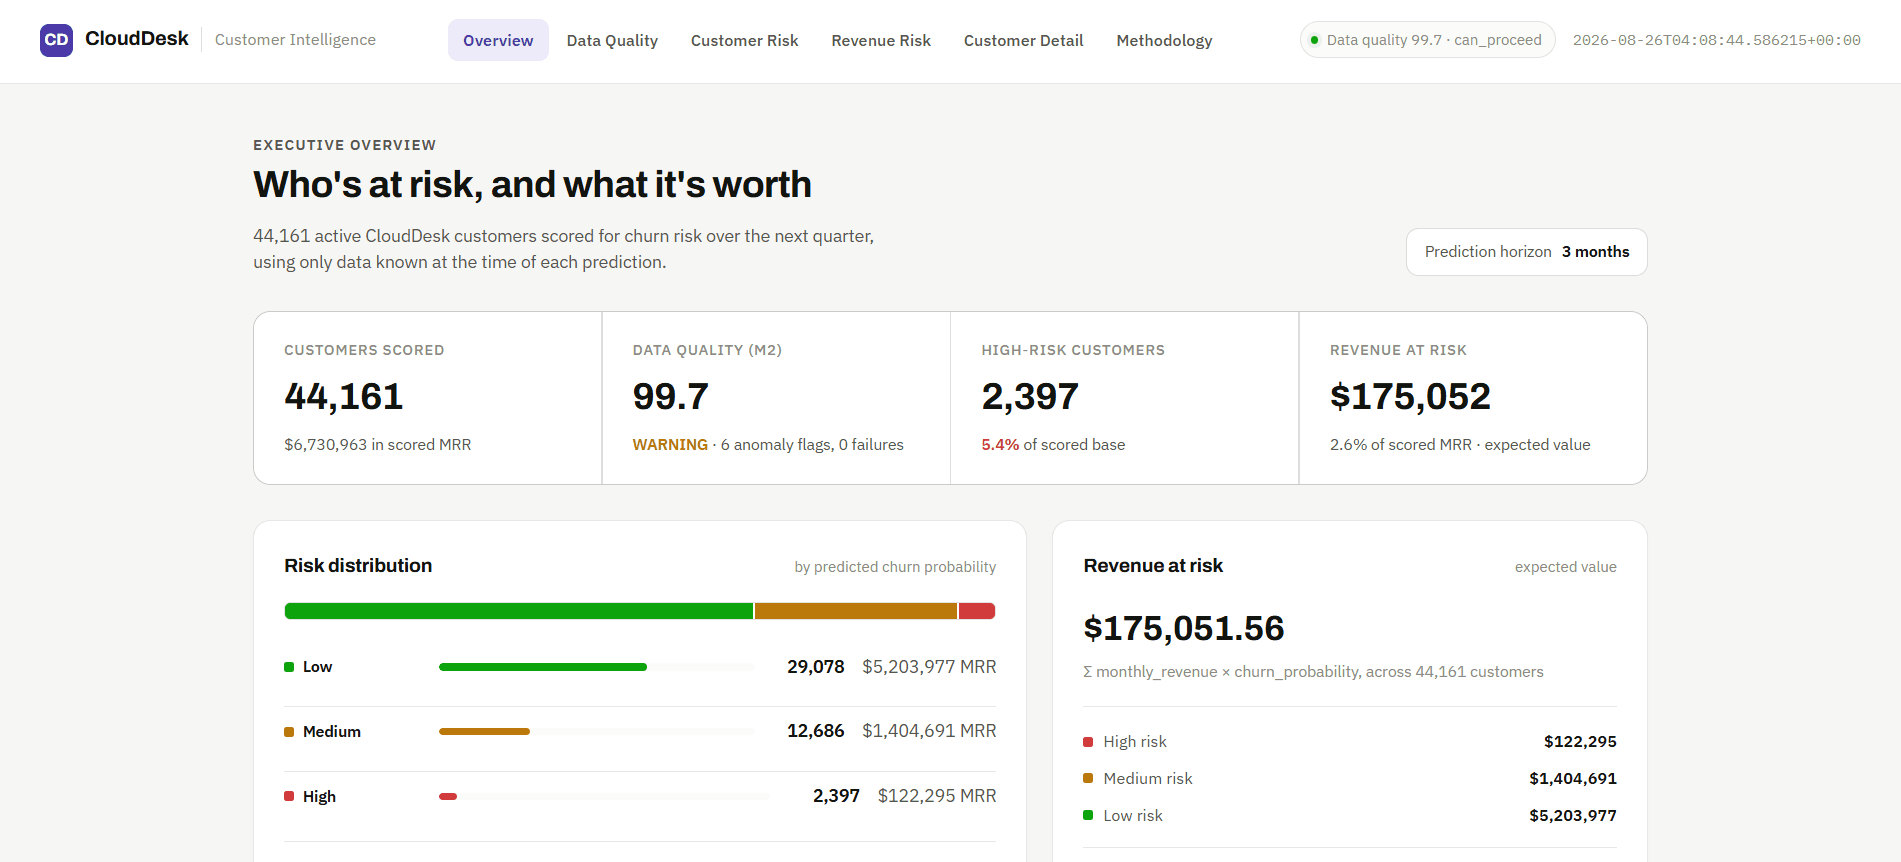
Six milestones are complete, from synthetic data generation through a real-world-data ingestion and hardening pass, each blocking the next via an explicit readiness gate. A seventh — commercial packaging — is in progress. A full pipeline run on the synthetic book scores roughly $6.73M in total recurring revenue with about $175K flagged at risk. The dashboard is currently a static-site generator reading real pipeline output rather than a live backend — a deliberate scoping choice, with a live API and per-customer interactivity as the natural next milestone.
What I Learned
The subtlest bug wasn't in the model — it was in how its probabilities got used afterward. Standard class-rebalancing techniques left the model's raw probability output badly miscalibrated for this data (predicting a roughly 43% average churn chance against a true ~3% base rate), which quietly broke both the risk-tier thresholds and the revenue-at-risk math downstream. Removing the rebalancing and anchoring risk thresholds to the model's actual calibrated output — instead of round numbers — fixed both, without hurting the model's ranking ability (0.7069 ROC-AUC). Later, a hardening pass deliberately scoped out adding product features (no auth, billing or multi-tenancy) to focus purely on reliability — reproducibility was re-run and diffed field-by-field, and a full secrets audit came back clean.